Articles on full-stack engineering, architecture, and building for the web by Farrukh Bilal.
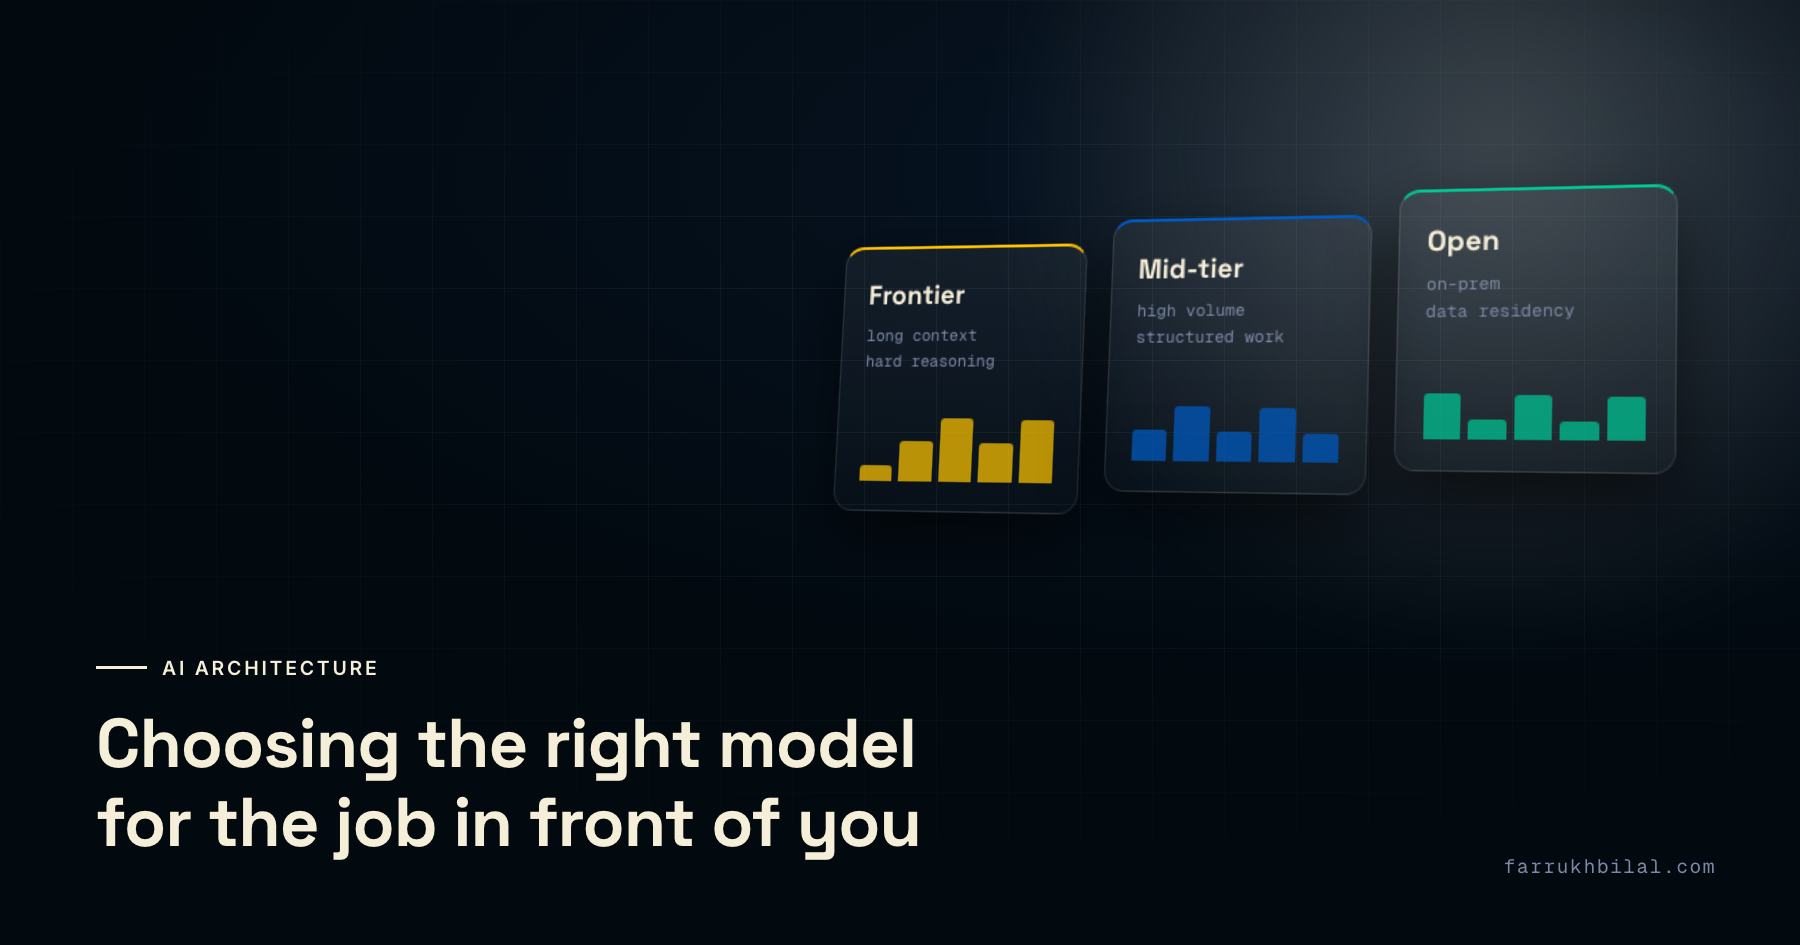
There's no single best model — there's a best model for your constraints. A practical framework for picking an LLM based on task, latency, cost, and data sensitivity.
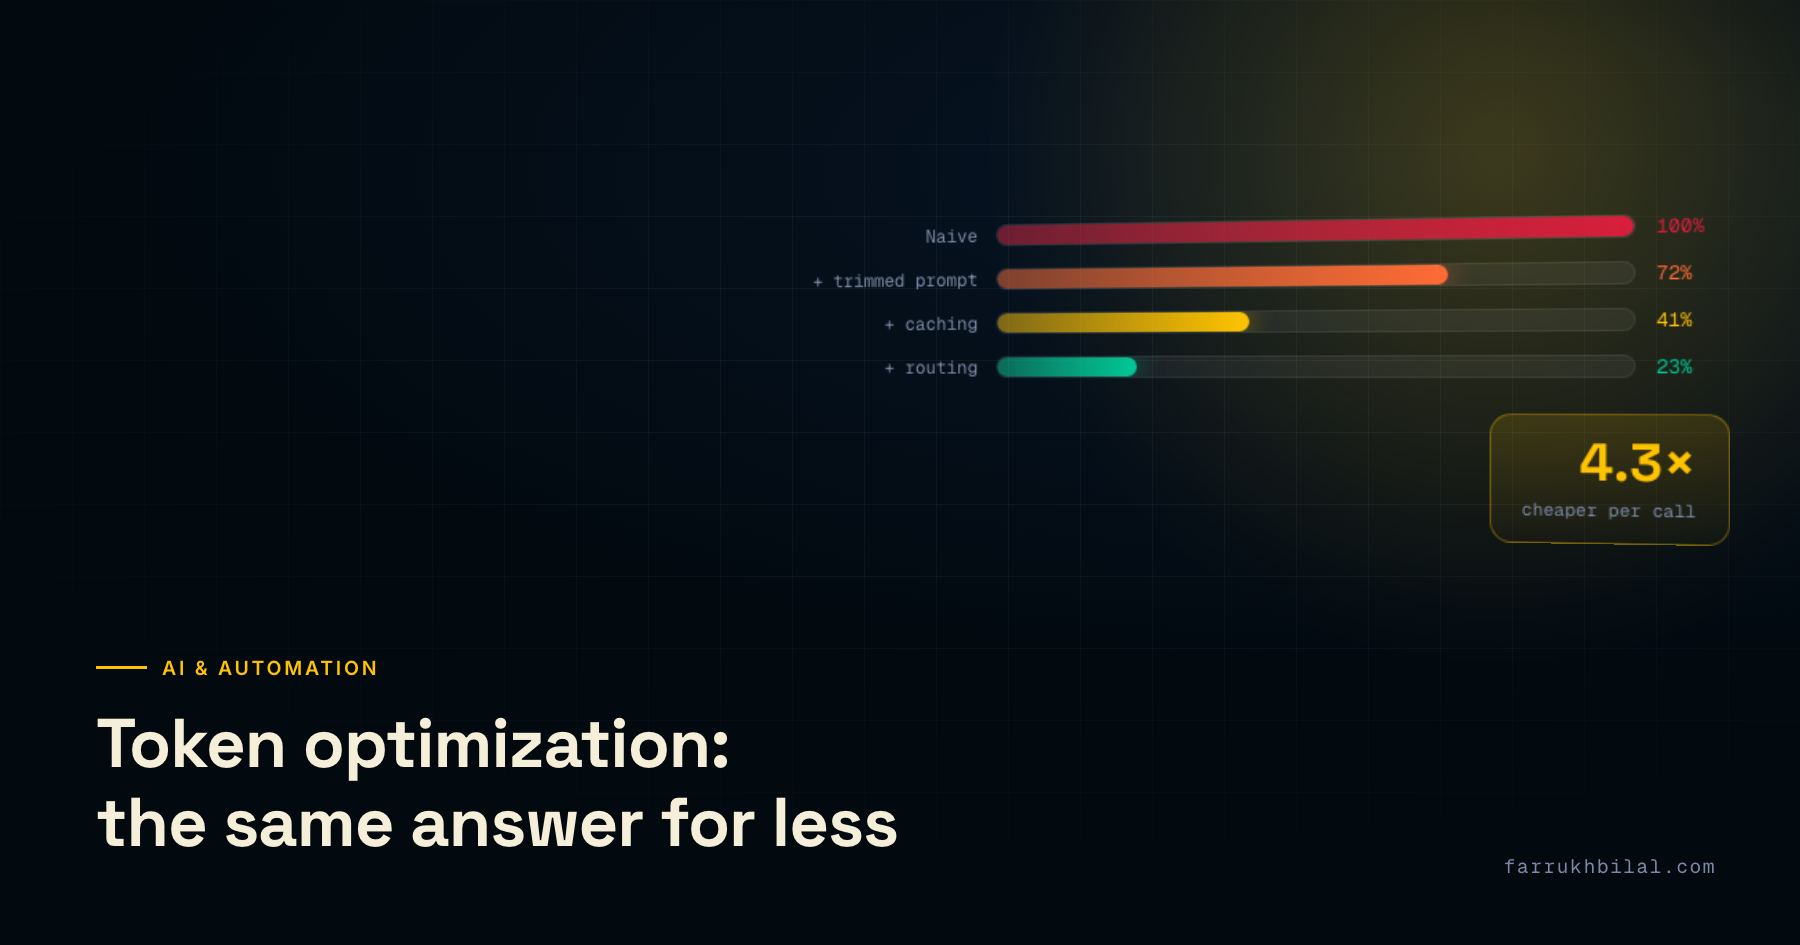
Practical techniques for reducing token spend in production LLM systems — prompt design, caching, model routing, and knowing when a smaller model is enough.
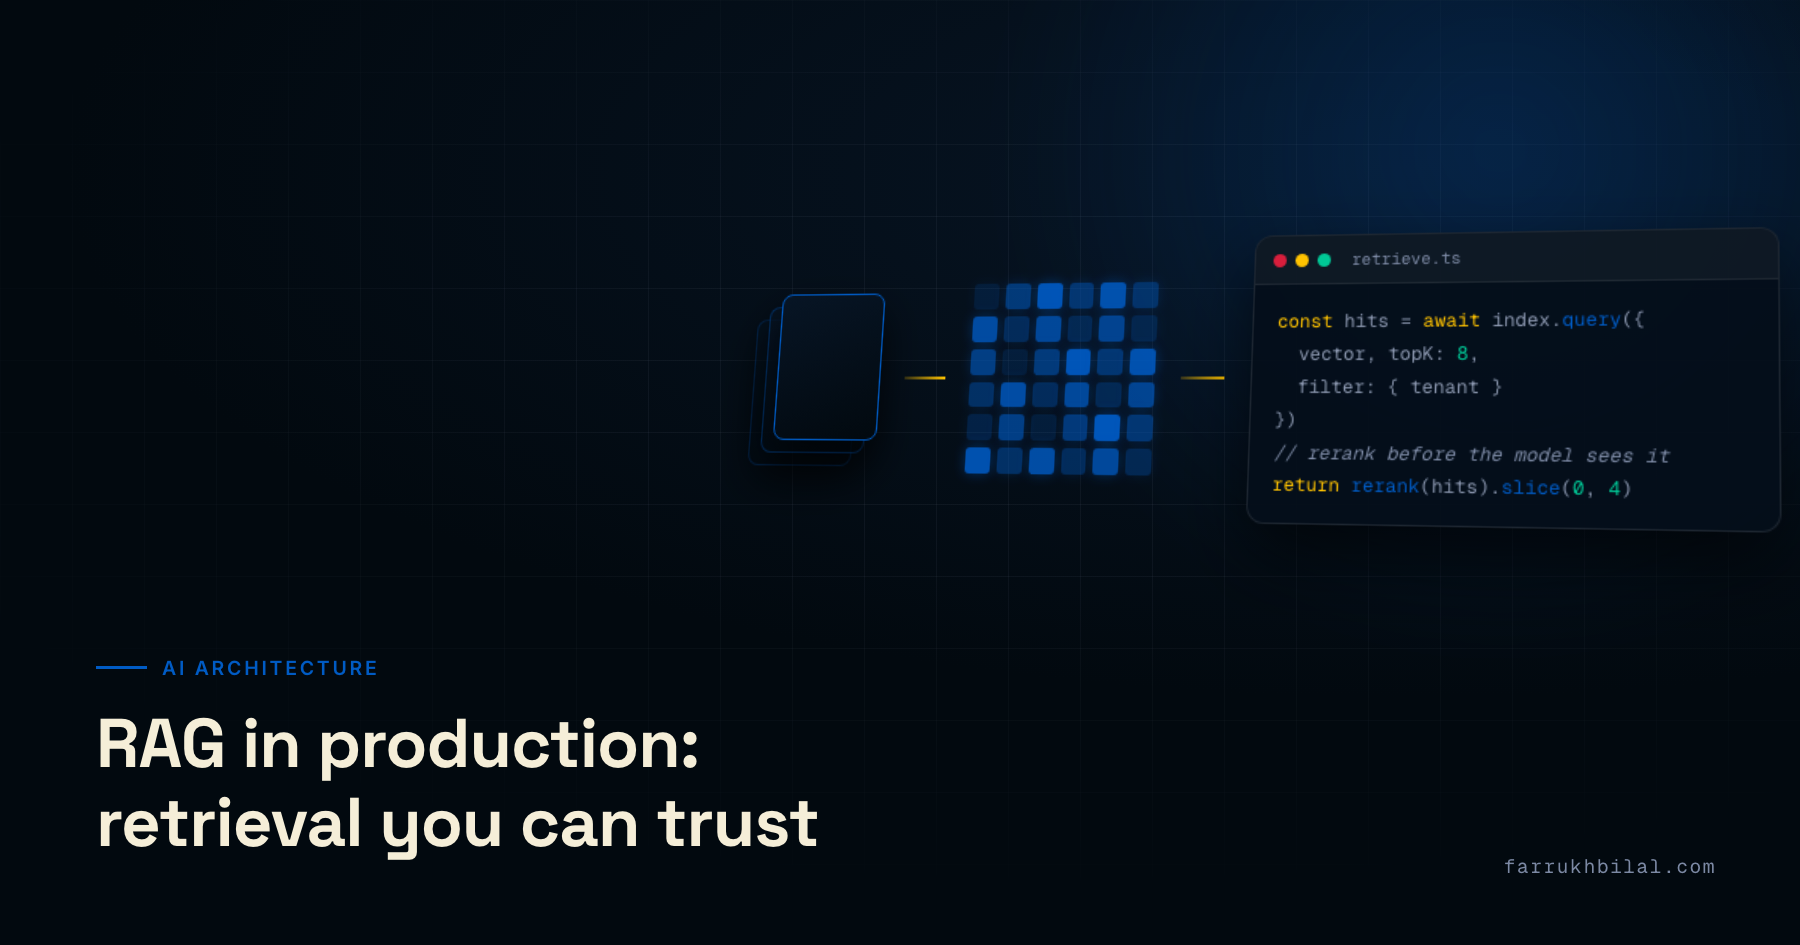
Retrieval-augmented generation looks simple in a tutorial. Here's what actually breaks when you put it in front of real documents and real users.
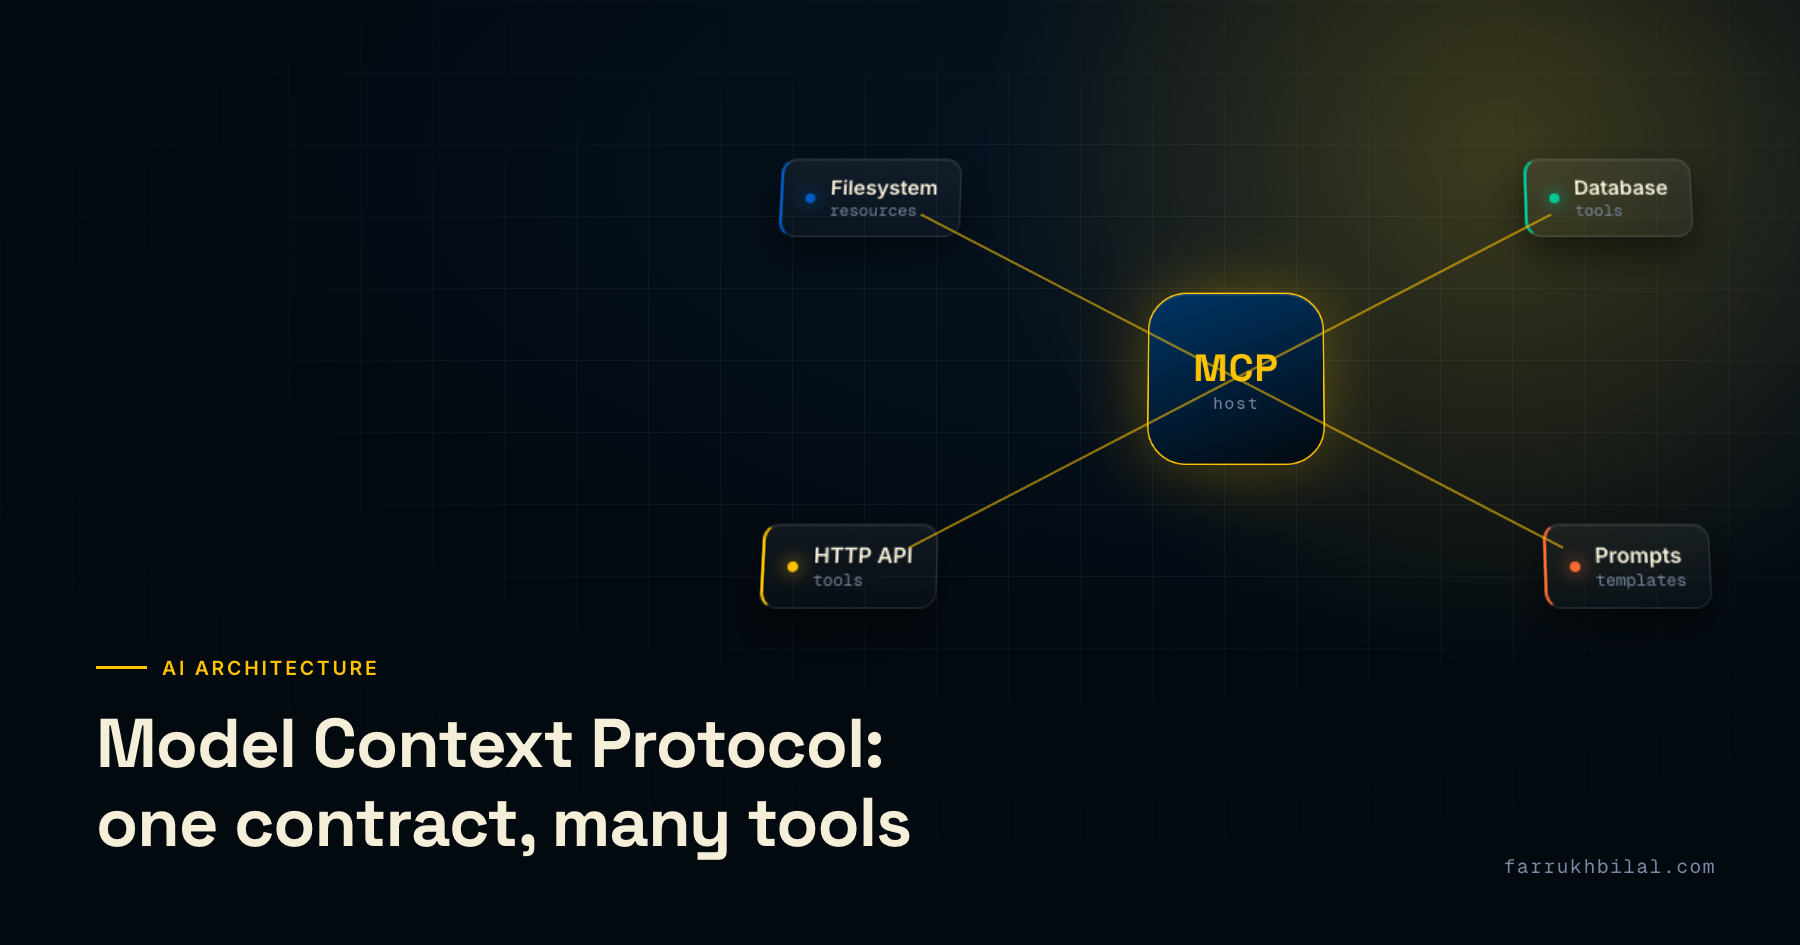
What MCP actually standardizes, why it matters for AI architecture, and how it changes the way LLMs connect to your APIs, databases, and internal tools.
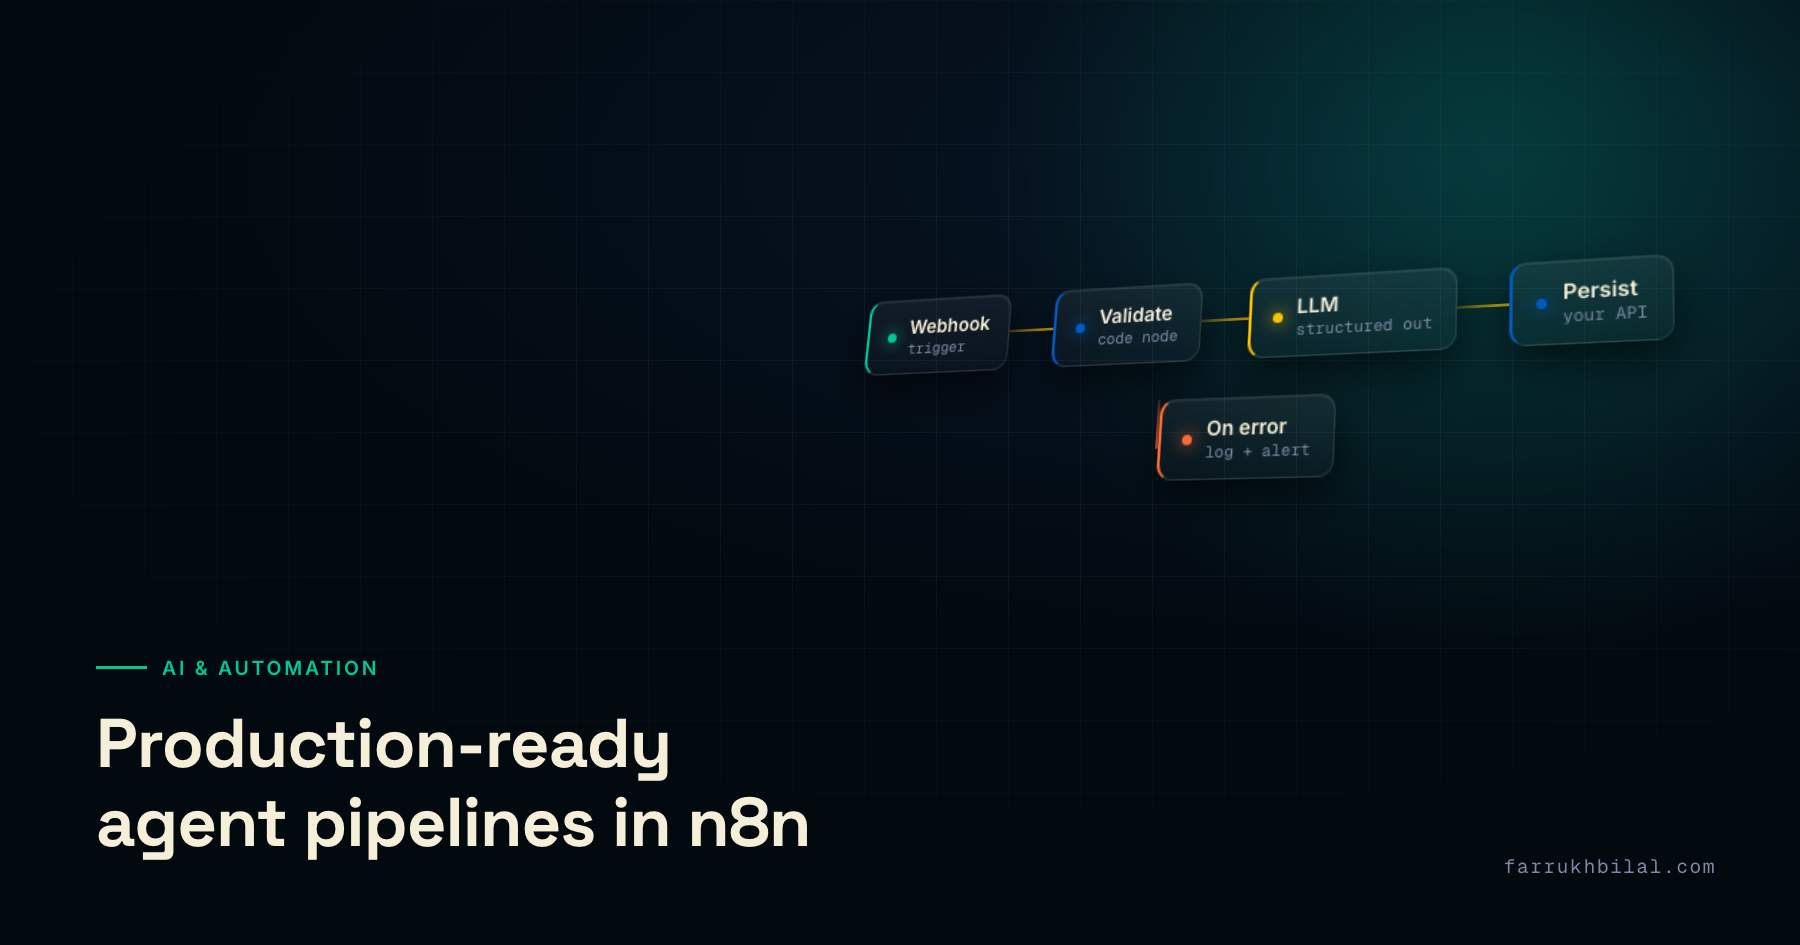
How I use n8n to orchestrate AI agents and automation pipelines in production — from trigger to LLM call to error handling that doesn't fail silently.